The idea: copy through the kernel, or share one page
Two processes have separate address spaces: A cannot read B's memory, and B cannot read A's. To work together they need inter-process communication (IPC), and there are two basic styles. In message passing (a pipe, a message queue, a socket) the sender hands bytes to the kernel and the receiver asks the kernel for them. In shared memory both processes map the same physical page and read and write it directly.
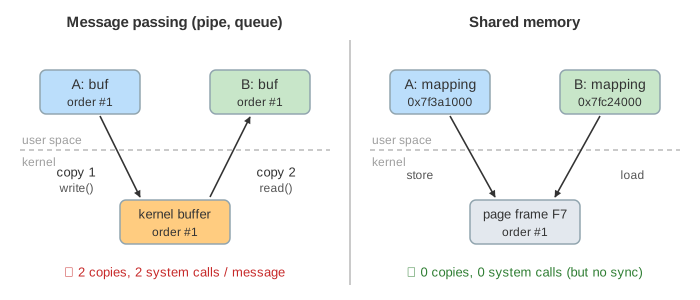
On the canvas, process A (the producer) has four 4 KiB messages for process B (the consumer): order #1, order #2, cancel #1 and order #3. Pick a mechanism, then press Send and Receive. The counters at the bottom add up the bytes the kernel copied and the system calls on the data path; the one-time setup is not counted.
Pipes: a byte stream
A pipe is a buffer in kernel memory with a write end and a read end. On Linux it is a ring of 16 pages, 64 KiB (fcntl(F_GETPIPE_SZ) shows it). write(fd[1], buf, 4096) is a system call in which the kernel copies the 4096 bytes from A's buffer into a pipe page. read(fd[0], buf, 8192) is a second system call that copies them out into B's buffer. Each byte crosses the kernel twice (Demo: pipe, copy in and copy out).
A pipe stores bytes, not messages. When A writes order #1 and order #2 before B reads, one read of 8 KiB returns both glued together (Demo: pipe glues two writes together). The receiver must find the message ends itself, with a newline, a length prefix or fixed-size records. The same is true of a TCP socket. How the shell connects ls | grep with a pipe is on How the Shell Runs ls | grep foo.
Message queues: whole messages, by priority
A POSIX message queue (mq_open("/orders", …)) is also kernel memory, so it costs the same two copies and two system calls per message. The difference is what it stores: each mq_send is one message with its own length and a priority, and each mq_receive returns exactly one whole message, the highest priority first and the oldest first within a priority. In Demo: message queue, whole messages by priority, cancel #1 (priority 9) is sent last and received first. Linux limits a queue to mq_maxmsg messages (default 10) of at most mq_msgsize bytes (default 8192); a full queue blocks mq_send.
Shared memory: map the same frame
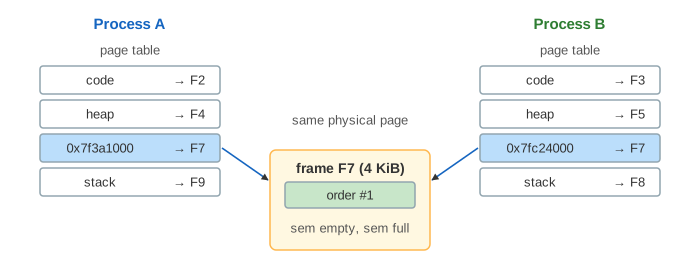
For shared memory each process calls shm_open("/orders", O_CREAT | O_RDWR) (a file in /dev/shm), sets its size once with ftruncate, and calls mmap(…, MAP_SHARED, fd, 0). The kernel puts the same physical page frame into both page tables, usually at different virtual addresses. These few system calls happen once. After that, A writes a message with ordinary store instructions, and B sees the bytes with ordinary loads: no copy by the kernel and no system call (Demo: shared memory, zero copies).
Shared memory needs its own synchronization
A pipe and a queue synchronize for you: read on an empty pipe puts B to sleep until data arrives (Demo: reader blocks on an empty pipe), and a full one blocks the writer. Shared memory does none of this. The page uses two semaphores stored in the shared page itself, the classic bounded-buffer pattern with a one-message slot: empty (starts at 1) and full (starts at 0). A does sem_wait(&empty), stores the message, sem_post(&full); B does sem_wait(&full), reads, sem_post(&empty). A process-shared semaphore is an atomic counter plus a futex: when the count allows it, sem_wait and sem_post are a single atomic instruction in user space, and only sleeping (FUTEX_WAIT) or waking a sleeper (FUTEX_WAKE) enters the kernel (Demo: shared memory, slot full so A waits).
Without the semaphores, nothing stops B from reading while A is halfway through a store. In Demo: shared memory without a lock, B gets the first 2 KiB of order #2 and the last 2 KiB of order #1: a torn read, a message that was never sent. The same race on threads is on Process vs Thread, and the full producer-consumer pattern is on Bounded Buffer.
Which one to use
| Pipe | Message queue | Shared memory | |
|---|---|---|---|
| Copies per message | 2 (in and out of the kernel) | 2 | 0 |
| System calls per message | 2 | 2 | 0, or 1 to sleep or wake |
| Message boundaries | No: a byte stream | Yes, plus priorities | Whatever layout you design |
| Synchronization | Built in: blocks when empty or full | Built in | Yours: semaphores, mutexes, atomics |
| Who can use it | Related processes (or a named FIFO) | Any process that knows the name | Any process that maps the name |
| Good for | Streams between a parent and child, shell pipelines | Small commands and events with priorities | Large data at high rates: databases, video frames, X11/Wayland buffers |
Copying 4 KiB takes well under a microsecond, so for small messages the system calls cost more than the copies, and the simplicity of a pipe or a queue usually wins. Shared memory pays off when the data is large or very frequent. PostgreSQL, for example, keeps its buffer cache in shared memory used by every backend process (see PostgreSQL Process Architecture).
A microkernel builds the whole OS on IPC; see Monolithic Kernel vs Microkernel for one read() sent as messages.
What the page leaves out
The page uses one producer and one consumer, four fixed messages and a one-slot shared buffer. It leaves out System V IPC (msgget, shmget, semget), named FIFOs (mkfifo), Unix domain sockets and file-descriptor passing, signals, vmsplice and other zero-copy pipe tricks, the 4096-byte PIPE_BUF atomicity rule for many writers, O_NONBLOCK and EAGAIN, mq_notify, a full ring buffer in shared memory, memory ordering (barriers), and the page fault that first maps the shared frame. Virtual-to-physical mapping is on Linux Virtual Memory.
See where this page fits on the Operating Systems mind map.