The idea: one slow dependency, every thread waiting
order-api builds a page from two downstream services. payment must work. recommendations is nice to have: if it fails, the page shows a cached list instead. Every tick, 2 calls to recommendations and 1 call to payment arrive. order-api has 6 worker threads, and a call keeps its thread until the answer arrives or the call times out after 3 ticks.
Use the recommendations select to make the service slow or failing, then press Next Tick. Use the protection select to compare no protection, a circuit breaker, bulkheads, and both. The names and defaults follow Resilience4j, scaled down to small numbers.
Why slow is worse than down
A service that is down answers fast: connection refused, or a 500 after one tick. The caller frees the thread at once. A slow service is worse. Every call waits for the full timeout and holds a thread the whole time. With 2 new calls per tick and a 3-tick timeout, recommendations soon holds all 6 threads. From then on the payment call finds no free thread and fails, although payment-service is perfectly healthy. This is a cascading failure: the problem spreads from the service that broke to the services that depend on it (Demo 4: slow service, no protection).
Longer timeouts make it worse. Retries make it worse too: each retry takes another thread. The same mechanism appears in Latency vs Throughput (a queue grows once arrivals exceed capacity) and in Connection Pooling (callers wait for a pool that never has a free slot).
The circuit breaker
A circuit breaker wraps the calls to one dependency and records their outcomes in a sliding window. On this page that is the last 4 calls (slidingWindowSize = 4, COUNT_BASED; a TIME_BASED window counts the calls of the last N seconds). Errors and timeouts count as failures. It has three states:
| state | what happens to a call | leaves when |
|---|---|---|
| CLOSED | sent; its outcome is recorded | the window has at least minimumNumberOfCalls (4) and the failure rate reaches failureRateThreshold (50%) → OPEN |
| OPEN | not sent: it fails at once with CallNotPermittedException | waitDurationInOpenState (3 ticks) has passed → HALF_OPEN |
| HALF_OPEN | the first permittedNumberOfCallsInHalfOpenState (2) calls are sent as trials; the rest are not permitted | the trials are done: failure rate below 50% → CLOSED, otherwise → OPEN |
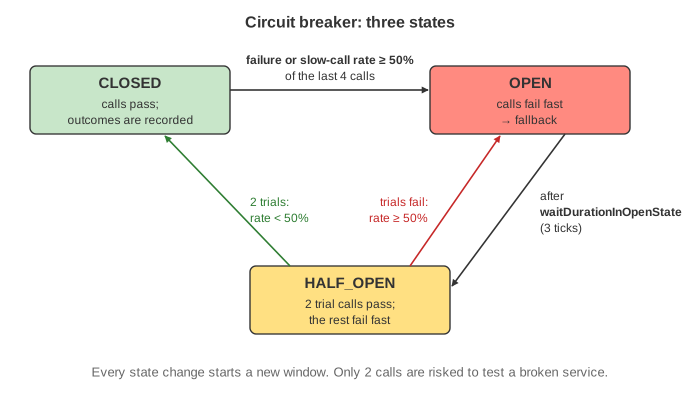
In OPEN, the caller does not wait at all: a refused call takes no thread and no time (Demo 1: errors trip the breaker). That also gives the broken service time to recover, because nobody keeps hammering it. Every state change starts a new window. The answers to calls sent before the change are ignored.
Resilience4j can also open on slow calls: calls slower than slowCallDurationThreshold count as slow, and the breaker opens when slowCallRateThreshold is reached, even if they succeed. On this page a slow call always reaches the 3-tick timeout, so it counts as a failure anyway (Demo 5: slow service, circuit breaker).
HALF_OPEN: is it back?
After the wait, the breaker does not simply close. It lets a few trial calls through and judges by them. If recommendations has recovered, the trials succeed and the breaker closes (Demo 2). If not, it opens again for another wait (Demo 3). Only 2 calls are risked to find out, not the full traffic. Real breakers often wait longer after each failed trial (exponential backoff of the open time).
Fallbacks
Failing fast only helps if the caller has something else to do. For recommendations it does: a cached or default list, so the page still renders. Payment has no sensible fallback: a refused payment is an error the user sees. That is why the breaker on this page protects recommendations, and why payment must be kept away from its trouble.
The bulkhead
A ship's hull is split into watertight compartments, so one leak does not sink the ship. A bulkhead does the same for threads: it caps the concurrent calls to each dependency (maxConcurrentCalls = 3). A call over the cap is rejected at once with BulkheadFullException (maxWaitDuration = 0). Recommendations can then hold at most 3 threads, however slow it gets, and payment always has its own 3 (Demo 6).
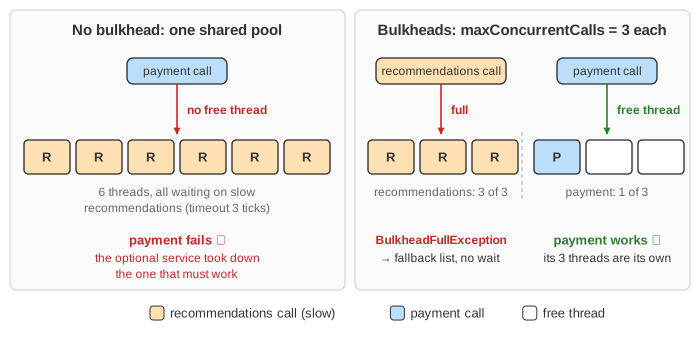
Resilience4j has two kinds. The semaphore bulkhead counts concurrent calls on the caller's threads, which is what the page shows. The thread-pool bulkhead runs each dependency's calls on its own fixed pool with a bounded queue. Netflix Hystrix made that kind well known.
Breaker and bulkhead together
The bulkhead works from the first tick, but it keeps sending calls to a broken service: 3 threads stay blocked forever. The breaker needs a few failures before it opens. Until then the damage spreads (in Demo 5, payment fails at t = 3 and t = 4). After that it stops sending altogether. Together, the bulkhead limits the damage at once and the breaker stops the waste.
| slow recommendations, 6 ticks | payments failed | threads held by recommendations |
|---|---|---|
| no protection | 4 (from t = 3 on) | all 6 |
| circuit breaker | 2 (until the breaker opens at t = 5) | 6, then 0 |
| bulkhead | 0 | 3, always |
| breaker + bulkhead | 0 | 3, then 0 |
In Resilience4j the decorators are applied in the order Retry ( CircuitBreaker ( RateLimiter ( TimeLimiter ( Bulkhead ( call ) ) ) ) ). A retry outside the breaker means a retried call that hits an OPEN breaker fails fast instead of waiting. A retry should not retry CallNotPermittedException.
See also Saga vs Two-Phase Commit: a saga step that keeps failing is a good place for a breaker.
See also How an API Gateway Handles a Request, where the gateway answers 502 and 504 for a failing service.
To find which downstream call is slow or failing in the first place, see Distributed Tracing with OpenTelemetry.
See also Monolith vs Microservices: what a crash, a deploy and a lost reply cost in each shape.
What the page leaves out
Time-based windows; the slow-call rate as a separate threshold; retries and their backoff; rate limiters; breakers on several instances of a service (one breaker per instance or per service); the downstream service still working on calls the caller has already given up on; queueing in front of the thread pool; and the metrics and events a real breaker publishes.