The idea: you write SELECT first, the database runs it fifth
A query is written SELECT … FROM … WHERE … GROUP BY … HAVING … ORDER BY … LIMIT. It is evaluated in a different order, the logical order: FROM → WHERE → GROUP BY → HAVING → SELECT → ORDER BY → LIMIT. Each step takes a table and hands a new table to the next one. The SQL standard defines the answer by this order, and MySQL and PostgreSQL both must return the same rows as if they followed it. Almost every "why is this an error?" question about these clauses is answered by asking which step a name is used in, and whether it exists yet.
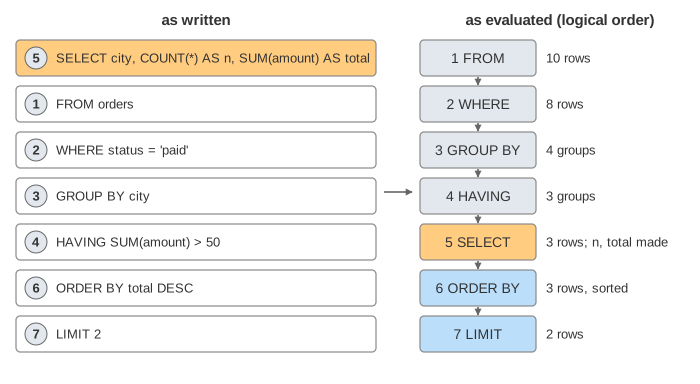
The page uses one small table, orders (id, city, amount, status), with 10 rows. Two rows are refunded and two have no city (NULL). The main query is:
SELECT city, COUNT(*) AS n, SUM(amount) AS total
FROM orders
WHERE status = 'paid'
GROUP BY city
HAVING SUM(amount) > 50
ORDER BY total DESC
LIMIT 2;| step | what it does | table after it |
|---|---|---|
| 1 FROM | start from the table | 10 rows |
| 2 WHERE | keep a row if status = 'paid' | 8 rows (4 and 7 dropped) |
| 3 GROUP BY | one group per city; both NULLs in one group | 4 groups: HN, SG, NULL, DN |
| 4 HAVING | keep a group if SUM(amount) > 50 | 3 groups (DN with 35 dropped) |
| 5 SELECT | one output row per group; makes n and total | HN 2 110, SG 3 95, NULL 2 75 |
| 6 ORDER BY | sort by total descending | HN, SG, NULL |
| 7 LIMIT | keep the first 2 | HN 2 110, SG 3 95 |
Before any row is read, the parser checks every name against what exists at that point. That is why an error such as "unknown column" comes back at once, even on a huge table. The page shows that check as a walk through the clauses in logical order, with the names the current clause can see on the right (Demo: the whole pipeline, step by step).
WHERE filters rows, HAVING filters groups
WHERE runs before grouping and looks at one row at a time. There is no group yet, so an aggregate such as SUM(amount) can't be used there: MySQL says ERROR 1111: Invalid use of group function, PostgreSQL says aggregate functions are not allowed in WHERE. HAVING runs once per group, after GROUP BY, so it can (Demo: an aggregate goes in HAVING, not WHERE).
A condition that uses no aggregate, such as city <> 'DN', gives the same rows in either clause. But in WHERE the rows are dropped before they are grouped, which is less work. PostgreSQL's planner moves such a condition from HAVING into the scan filter for you. MySQL runs it where you wrote it, and its manual says not to put WHERE conditions in HAVING (Demo: HAVING without an aggregate).
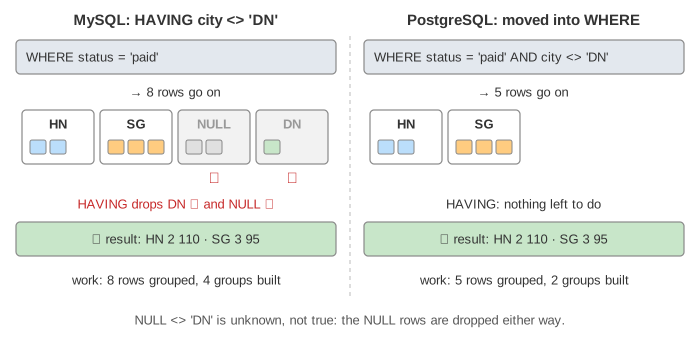
Watch the NULL group: NULL <> 'DN' is unknown, not true, so both WHERE and HAVING drop it.
After GROUP BY, a row is a group
GROUP BY city turns the 8 paid rows into 4 groups. From then on each "row" stands for a whole group, so only these have one value per group: the grouping columns, aggregates (COUNT(*), SUM(amount), MIN(id)…), and columns functionally dependent on the grouping columns (if you group by the primary key id, every other column of the row is fixed too). All NULL keys go to one group, even though NULL = NULL is not true.
SELECT city, id, SUM(amount) … GROUP BY city asks for "the id" of the HN group, which has ids 1 and 3. PostgreSQL always refuses: column "orders.id" must appear in the GROUP BY clause or be used in an aggregate function. MySQL refuses too while sql_mode contains ONLY_FULL_GROUP_BY (the default since 5.7: ERROR 1055). Without it, MySQL returns any id from the group, with no warning. Use ANY_VALUE(id) when that is really what you want (Demo: column not in GROUP BY, and ONLY_FULL_GROUP_BY off).
Since MySQL 8.0, GROUP BY no longer sorts its result. Neither engine promises any order unless you write ORDER BY.
Where SELECT aliases can be used
An alias such as total is made in step 5. Standard SQL lets only ORDER BY use it, since that is the only later step. Both engines bend the rule a little:
| clause | MySQL 8.4 | PostgreSQL 17 |
|---|---|---|
WHERE total > 50 | ✗ ERROR 1054 Unknown column | ✗ column does not exist |
GROUP BY alias | ✓ (extension) | ✓ (extension) |
HAVING total > 50 | ✓ (extension) | ✗ column "total" does not exist |
ORDER BY total | ✓ | ✓ |
ORDER BY total + 1 | ✓ | ✗ an alias only works on its own, not in an expression |
One more PostgreSQL detail: if an alias has the same name as a table column, GROUP BY picks the table column and ORDER BY picks the alias (Demo: WHERE can't use a SELECT alias, Demo: alias in HAVING).
ORDER BY and LIMIT come last
ORDER BY sorts the rows SELECT made; LIMIT n (with OFFSET m) keeps a slice of them. Without ORDER BY the order is whatever the plan produced, and it can change when the data or the plan changes, so LIMIT without ORDER BY picks arbitrary rows.
The two engines disagree on NULL. MySQL treats NULL as smaller than any value: first in ASC, last in DESC. PostgreSQL treats it as larger: last in ASC, first in DESC, and lets you choose with NULLS FIRST / NULLS LAST. In MySQL write ORDER BY city IS NULL, city to put NULLs last (Demo: NULL is one group; where NULLs sort).
The engine may take shortcuts
The logical order defines the answer, not the work. An engine may push filters down, read an index that is already sorted by the group key so no hash table is needed, or keep only the top rows while sorting for a LIMIT. The EXPLAIN panel on the canvas shows the plan each engine picks for the query (read it from the bottom up). For the main query:
MySQL                                        PostgreSQL
-> Limit: 2 row(s)                           Limit
  -> Sort: total DESC, limit input to 2        -> Sort  (Sort Key: sum(amount) DESC)
    -> Filter: (sum(amount) > 50)                -> HashAggregate  (Group Key: city)
      -> Table scan on <temporary>                    Filter: (sum(amount) > 50)
        -> Aggregate using temporary table           -> Seq Scan on orders
          -> Filter: (status = 'paid')                    Filter: (status = 'paid')
            -> Table scan on orders
How these operators move rows (hash joins, temporary tables, filesort, HashAggregate vs GroupAggregate, sorts that spill to disk) is the subject of How MySQL Executes JOIN, GROUP BY and ORDER BY and How PostgreSQL Executes JOIN, GROUP BY and ORDER BY. How the plan is chosen is in How a Query Planner Picks a Plan.
MySQL vs PostgreSQL in one table
| topic | MySQL 8.4 | PostgreSQL 17 |
|---|---|---|
| alias in HAVING | allowed | error |
| non-grouped column in SELECT | error with ONLY_FULL_GROUP_BY (default); any value without it | always an error (unless functionally dependent on the primary key) |
NULL in ORDER BY … ASC | first | last (NULLS FIRST/LAST to choose) |
| HAVING condition with no aggregate | run after grouping | moved into WHERE by the planner |
| error codes | 1054 unknown column, 1111 group function, 1055 only_full_group_by | SQLSTATE 42703 undefined column, 42803 grouping error |
What the page leaves out
Joins (a FROM with several tables is built first, then WHERE runs on the joined rows), window functions (they run after HAVING and before ORDER BY, so they can't be used in WHERE either), DISTINCT and PostgreSQL's DISTINCT ON (between SELECT and ORDER BY), ROLLUP / GROUPING SETS, subqueries and CTEs, and collations, which decide how text compares and sorts. The EXPLAIN output is shortened, and the real parser checks names in its own order, not clause by clause.