The idea: two trees over the same array
You have an array A[1..n] that changes, and you keep asking for the sum (or the min) of a range A[l..r]. Adding up the range each time costs O(n). A segment tree and a Fenwick tree (also called a binary indexed tree, BIT) both store sums of blocks of the array, so a query or an update only touches O(log n) blocks. This page builds both over A = 5 2 7 1 4 6 3 8 and runs every operation in both at once, one node per step.
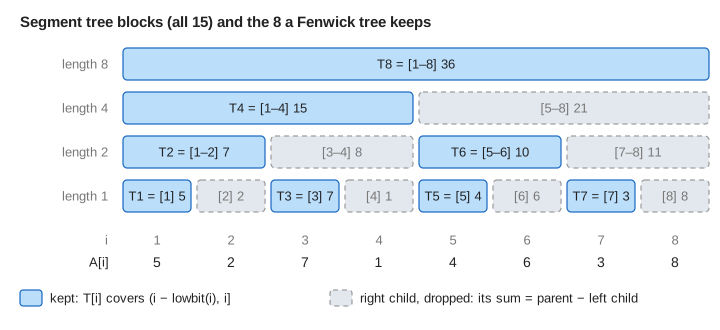
The segment tree stores every block: the whole array, its two halves, their halves, down to single positions. That is 2n − 1 nodes (code that stores it in an array usually allocates 4n). Each node can hold anything you can combine from its two children: a sum, a min, a max, a count.
The Fenwick tree throws away every right child. Its cell T[i] holds the sum of A over (i − lowbit(i), i], where lowbit(i) = i & −i is the lowest 1-bit of i. So T[6] covers 5..6 and T[8] covers 1..8. That is exactly n numbers, and the code is a few lines.
Prefix and range sums
A Fenwick tree answers a prefix sum prefix(i) = A[1] + … + A[i] by reading T[i] and stripping the lowest bit, i −= lowbit(i), until i is 0. It reads one cell per 1-bit of i: prefix(7) reads T[7], T[6], T[4] (Demo: prefix sum A[1..7]).
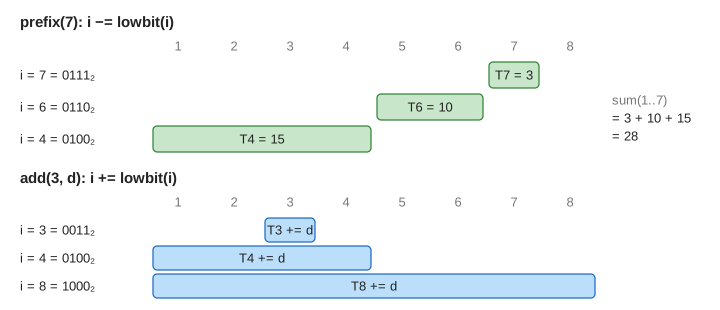
A range sum is two prefix sums subtracted: sum(l..r) = prefix(r) − prefix(l − 1) (Demo: range sum A[3..6]). The segment tree instead starts at the root: a block that lies fully inside [l, r] is read and the walk stops there; a block that is only partly inside sends the walk to its children. At most about two blocks per level are partly inside, so it touches O(log n) nodes, usually a few more than the Fenwick tree.
Point updates
To add d to A[i], the Fenwick tree does T[i] += d and climbs with i += lowbit(i): each step lands on the next block that contains position i. The segment tree walks down to the leaf and then recomputes each parent's sum and min on the way back up: the leaf and all its ancestors, log n + 1 nodes (Demo: point add +3 at A[3]).
Range min: where the Fenwick tree stops
The trick prefix(r) − prefix(l − 1) only works because subtraction undoes addition. Min has no inverse: knowing the min of 1..7 and the min of 1..1 tells you nothing about the min of 2..7. So a Fenwick tree handles sum, count and xor, but not range min or max (it can still do prefix min if values only go down). The segment tree just stores a min in every node and answers the same way as a sum (Demo: range min A[2..7]).
Range add and lazy propagation
Now add d to every position in [l, r]. The segment tree uses lazy propagation: when a block lies fully inside the range it adds d × length to its sum and d to its min, writes a lazy tag "my children still owe +d", and stops. A later operation that needs to go below a tagged block first pushes the tag to its two children (Demo: a later query pushes a lazy tag down). A range add therefore costs O(log n), like a query.
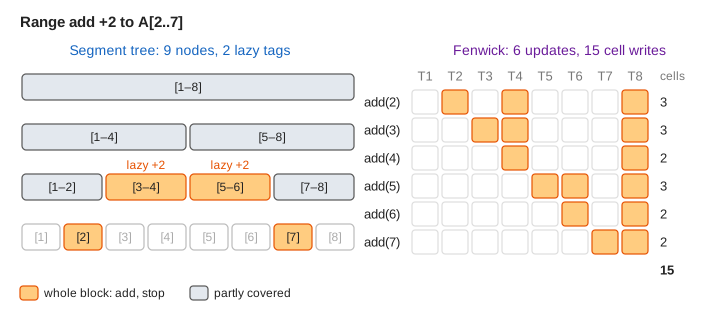
A plain Fenwick tree has no tags, so this page does one point update per position: O((r − l + 1) log n) (Demo: range add +2 to A[2..7]). There are known tricks: one BIT over the differences gives range add with point query, and two BITs give range add with range sum, each in O(log n). None of them gives range min.
Memory and speed
| Segment tree | Fenwick tree | |
|---|---|---|
| Numbers stored for n = 8 | 15 nodes × (sum, min, lazy) = 45 | 8 |
| Array size in typical code | 2n (iterative) or 4n (recursive) | n + 1 |
| Range sum | O(log n), about 2 nodes per level | O(log n), one cell per 1-bit, twice |
| Point update | O(log n), down and back up | O(log n), a tight loop |
| Range min / max | yes | no |
| Range add | yes, lazy tags | for sums only, with the two-BIT trick |
| Code | 40–80 lines, recursion | about 10 lines |
In practice the Fenwick tree is often 2–3× faster for sums: fewer numbers, no recursion and a loop the compiler handles well.
Which one to use
- Only sums (or xor, counts) with point updates: a Fenwick tree. Typical uses are counting inversions, order statistics over a value range, and running frequency tables.
- Min, max, gcd, or any combine without an inverse: a segment tree.
- Range updates mixed with range queries, or several values per node: a segment tree with lazy propagation.
Each structure also has a page of its own: Segment Tree and Fenwick Tree. The segment tree here uses the same array layout as a binary heap (node k has children 2k and 2k + 1); see Heaps. For another pair of structures compared side by side, see AVL vs Red-Black Tree.
What the page leaves out
The array has a fixed size of 8 and both trees are built before the page starts (building costs O(n) for both). Not shown: the iterative bottom-up segment tree, persistent and dynamic (sparse) segment trees, segment tree beats, 2D Fenwick trees, binary search on a Fenwick tree for the k-th element, sparse tables for static range min, and the two-BIT range-add code itself.