The idea: readers never wait
Some kernel data is read all the time and changed rarely: routing tables, the list of loaded modules, a process's open files. A lock, even a readers-writer lock, makes every reader write to a shared lock word. On many CPUs that cache line bounces between them and readers slow each other down.
Read-Copy-Update (RCU) lets readers take no lock at all. A writer never changes the shared data in place. It copies it, updates the copy, and publishes the copy by switching one pointer. Old readers keep the old version, new readers get the new one. The writer frees the old version only when no reader can still be using it.
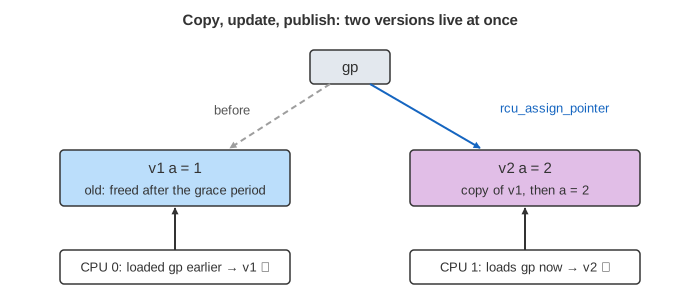
The read side
rcu_read_lock();
p = rcu_dereference(gp);
x = p->a;            /* use p, maybe for a while */
rcu_read_unlock();
In the classic kernel RCU, rcu_read_lock() just turns off preemption on this CPU. It writes nothing shared. rcu_dereference(gp) is a plain load of the pointer, with the ordering that later loads through p see the data the writer stored before publishing. Between the two calls is the read-side critical section. Inside it the reader may not sleep. (Demo: readers only, no locks: three CPUs read at once and nobody waits.)
Copy, update, publish
old = gp;
new = kmalloc(sizeof *new);
*new = *old;              /* copy   */
new->a = old->a + 1;      /* update */
rcu_assign_pointer(gp, new);   /* publish */
The copy is private until the publish, so readers never see a half-written struct. rcu_assign_pointer is a single pointer store with a release barrier: the new contents are visible before the new pointer. Writers still serialize against each other with an ordinary lock; RCU only removes the readers from the picture.
Grace periods and quiescent states
After the publish, a reader that loaded gp earlier may still hold the old pointer. The writer must wait until every such reader has left its critical section. That wait is a grace period.
RCU does not track readers one by one. It uses a cheaper fact: a reader can't be preempted inside its critical section, so once a CPU passes a quiescent state (a context switch, the idle loop, user mode), every critical section that was running on it has ended. When every CPU has passed a quiescent state after the grace period started, no reader can still hold the old version, and it is safe to free. On the canvas each tick, a CPU outside a read section reports its quiescent state, and the grace period ends when all three have.
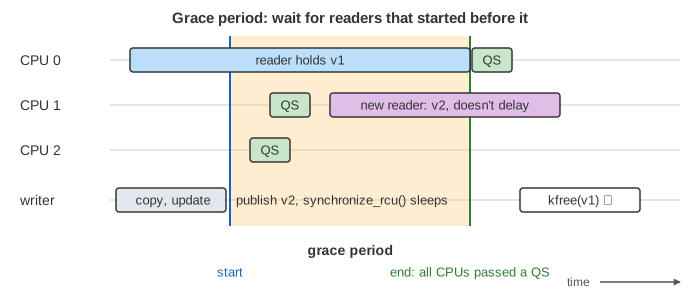
A long reader only delays the grace period. It never blocks other readers, and the writer has already published (Demo: a long reader delays the grace period). A reader that starts after the publish gets the new version, so it doesn't matter to the old one.
synchronize_rcu vs call_rcu
synchronize_rcu() | call_rcu(&old->rcu, free_old) | |
|---|---|---|
| The writer | sleeps until a grace period ends, then calls kfree(old) | queues a callback and returns at once |
| Freeing | in the writer, after the wait | the callback runs later, in softirq context |
| Can be called from | process context only (it sleeps) | anywhere, even with interrupts off |
| Cost | a whole grace period of latency per update | old versions use memory until their grace period ends |
A request that comes while a grace period is already running waits for the next one: the running one may have started before the new publish (Demo: call_rcu, the writer does not wait). On the canvas memory has only three slots, so many quick call_rcu updates run out of memory until a grace period frees some. The kernel has the same problem on a larger scale and throttles callback floods.
Freeing too early: use-after-free
Skip the grace period and call kfree(old) right after the publish, and a reader that still holds p has a dangling pointer. Its next p->a reads freed memory: slab poison (0x6b6b6b6b with debugging on), or worse, a new object that kmalloc put at the same address. The reader then gets a value from the wrong object with no error at all (Demo: bug, freeing too early: v3 lands in v1's slot and CPU 0 reads a = 3). These bugs are rare and timing-dependent, which is why the kernel has lockdep-RCU checks and KASAN.
When RCU fits
| Readers-writer lock | RCU | |
|---|---|---|
| Reader cost | atomic update of a shared counter | no shared write at all |
| Readers and writer at once | no: the writer waits for readers, readers wait for the writer | yes: readers see old or new |
| Writer cost | small | a copy plus a grace period |
| Data seen | always the newest | may be one version behind for a while |
RCU fits read-mostly data where a slightly stale view is fine. The publish is a single pointer store, the same idea compare-and-swap builds on. For the lock-based ways to share data between readers and writers, see the readers-writers problem and the readers-writer lock.
What the page leaves out
Real RCU tracks quiescent states in a tree of rcu_node structures so thousands of CPUs don't contend on one mask, and it detects them from the scheduler tick, context switches and idle entry rather than a fixed clock. Preemptible RCU (CONFIG_PREEMPT_RCU) lets readers be preempted and counts them per task instead. The page also skips SRCU (readers that may sleep), expedited grace periods, RCU-protected linked lists (list_add_rcu, list_del_rcu), callback batching and offloading, and the writer-side lock.