The idea: a 16 KB page is not written at once
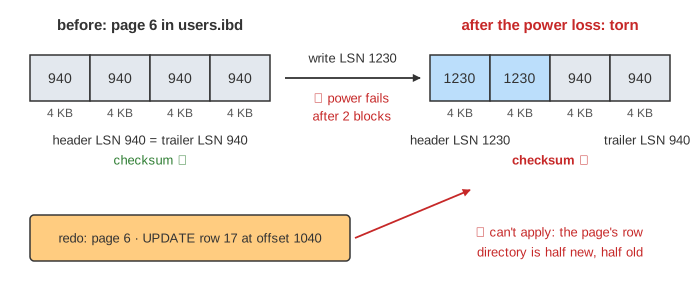
InnoDB keeps table data in 16 KB pages. The filesystem and the disk write in smaller units, usually 4 KB blocks, so one page write is really four writes. If the power fails in the middle, the page on disk is torn: the first blocks hold the new version, the rest the old one. Every page has its LSN twice, in the header (FIL_PAGE_LSN) and in the trailer, and a checksum over the whole page. A torn page has two different LSNs and a checksum that fails.
Why redo can't fix a torn page
The redo log already holds every committed change, so why not just replay it? Because InnoDB redo records are physiological: physical about the page ("page 6 of space 12"), logical inside it ("update row 17 at offset 1040"). Replay reads the page, compares its LSN with the record's and applies the change to the page's own structure: the record directory, the free space, the row headers. On a torn page none of that can be trusted. Redo also does not hold whole pages, so it cannot rebuild one from nothing. It needs a consistent base page, old or new, to work on.
The doublewrite buffer: write every page twice
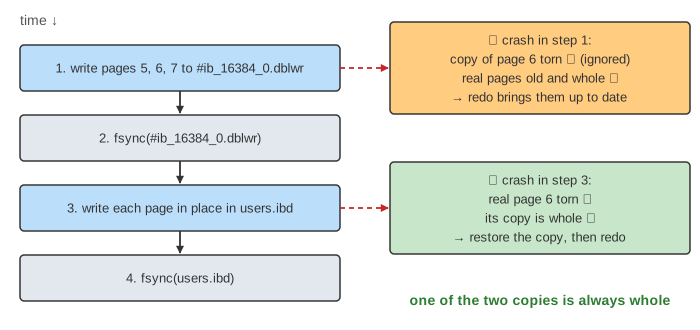
So InnoDB makes sure that a whole copy of each page is always somewhere on disk. When the page cleaner flushes a batch of dirty pages (see the buffer pool), it:
- copies the batch into the in-memory doublewrite buffer and writes it to the doublewrite file (
#ib_16384_0.dblwr) in one sequential write; - calls
fsync()on that file; - writes each page to its own place in its tablespace (
users.ibd, at offset page number × 16 KB); - calls
fsync()on the tablespace.
At any moment one of the two copies is whole. Until step 2 finishes, the real page has not been touched. After it, the copy is safe on disk. Demo: normal flush through the doublewrite file.
The cost is less than "twice the writes" sounds. The doublewrite write is one large sequential write per batch, and the data still goes to the redo log only once. Benchmarks usually show a few percent, more on write-heavy loads with slow fsync.
Recovery with the doublewrite copy
After a crash InnoDB reads the doublewrite file into memory and checks each copy's checksum. When crash recovery then reads a page of a tablespace and the page fails its checksum, InnoDB looks for an intact copy of the same page in the doublewrite pages and writes it over the torn one. Only then does redo run, from the checkpoint LSN: a record is applied only if it is newer than the page's LSN (see InnoDB crash recovery and the redo log). In Demo: crash in the in-place write, page 6 is restored at LSN 1230, page 5 was already written, and only the record for page 7 is applied.
A crash during the doublewrite write
If the power fails while the batch goes to the doublewrite file, it is the copy that is torn. That is harmless: step 3 had not started, so every page in the tablespace is still the old version, whole, with a good checksum. Recovery ignores the bad copy and redo brings the old pages up to date. Demo: crash in the doublewrite write.
| Crash during | Doublewrite copy | Real page | Recovery |
|---|---|---|---|
| doublewrite write | torn ✗ | old, whole ✓ | redo from the old page |
| in-place write, ON | whole ✓ | torn ✗ | restore the copy, then redo |
| in-place write, OFF | none | torn ✗ | corruption: mysqld won't start |
innodb_doublewrite and its files
With innodb_doublewrite = OFF InnoDB writes each page only once, straight to its place. That is faster, and on most crashes nothing happens, because no page write was in flight. But when one was, recovery finds the torn page, logs [ERROR] InnoDB: Database page corruption on disk and stops. The data that can still be read has to be dumped with innodb_force_recovery, or the server restored from a backup. Demo: innodb_doublewrite = OFF, torn page = corruption.
| Setting | Meaning |
|---|---|
innodb_doublewrite = ON (default; DETECT_AND_RECOVER in 8.0.30+) | pages go to the doublewrite file first; torn pages are detected and repaired |
DETECT_ONLY (8.0.30+) | only page metadata goes to the doublewrite file: an incomplete write is detected, but not repaired |
OFF | no doublewrite at all |
innodb_doublewrite_pages | pages per batch write (128 by default in 8.4; the canvas draws 3) |
innodb_doublewrite_files, innodb_doublewrite_dir | files per buffer pool instance (2 by default: one for flush-list batches, one for LRU / single-page flushes) and their directory, for example a fast SSD |
Before MySQL 8.0.20 the doublewrite buffer was a fixed area of 128 pages (two extents) inside the system tablespace, ibdata1.
Storage with atomic writes
The doublewrite is only needed because a 16 KB write can be torn. Some storage guarantees that it can't. ZFS is copy-on-write: a block is written to a new place and the pointer switched afterwards, so with recordsize=16k a page is either all old or all new. Some SSDs and NVMe devices, and the old FusionIO cards, promise atomic writes of 16 KB. MariaDB detects some of these devices and turns the doublewrite off by itself. On such storage innodb_doublewrite = OFF is safe, and DETECT_ONLY keeps a cheap check that the promise holds.
The same problem in PostgreSQL
PostgreSQL has 8 KB pages and the same torn-page problem. It solves it in the log instead: with full_page_writes = on, the first change to a page after each checkpoint puts a full-page image into the WAL, and replay restores that image before applying later records (see PostgreSQL WAL). InnoDB keeps its redo small and pays with a second page write; PostgreSQL writes each page once and pays with bigger WAL right after every checkpoint.
| InnoDB | PostgreSQL | |
|---|---|---|
| Where the whole copy lives | doublewrite file, written before the page | WAL record, the first change after a checkpoint |
| Extra cost | every page flush is written twice | more WAL after each checkpoint |
| Switch | innodb_doublewrite | full_page_writes |
See also How MySQL Runs a Query for where the page cleaner fits, and Write-Ahead Logging and ARIES for the general redo / undo rules.
SQLite makes a commit atomic either by saving the old pages in a rollback journal or by appending the new pages to a WAL; see SQLite internals.
What the page leaves out
Real batches hold up to innodb_doublewrite_pages pages from many tablespaces, and several page cleaner threads write their own batches. The page leaves out the second doublewrite file for LRU and single-page flushes, the doublewrite encryption of encrypted pages, O_DIRECT and the OS page cache, compressed and smaller page sizes (#ib_8192_0.dblwr, ...), sector sizes of 512 bytes, partial writes inside a 4 KB block, undo during recovery, and how the checkpoint really moves with the oldest modification LSN in the flush list.