The idea: the table is a tree, and every other index points into it
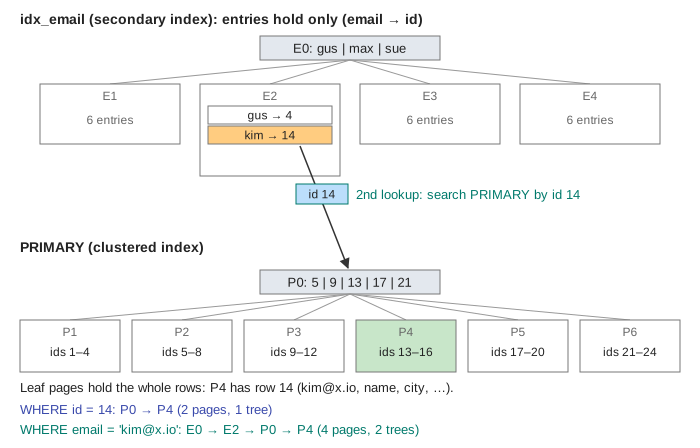
In MySQL's InnoDB engine the table is a B+ tree sorted by the primary key. Its leaf pages hold the whole rows. This tree is the clustered index. Any other index, such as idx_email, is a secondary index: a second B+ tree whose leaf entries hold only the indexed column and the primary key. The page runs two queries on the same 24-row table at the same time, one per lane, and counts the pages each one touches.
The clustered index (PRIMARY)
Rows are stored in primary-key order, a few per 16 KB page. WHERE id = 14 is one descent: read the root, pick the child, read the leaf, and the row is right there with every column (Demo: lookup by id vs by email). There is only one clustered index per table, because rows can be stored in only one order. If a table has no primary key, InnoDB uses the first UNIQUE NOT NULL index, or else adds a hidden 6-byte row id (GEN_CLUST_INDEX).
The secondary index and the second lookup
An idx_email entry is (email, id). To return SELECT * the engine takes the id from the entry and searches PRIMARY for it. This second descent is often called a bookmark lookup (SQL Server calls it a key lookup). InnoDB stores the primary key rather than a page address because rows move when pages split; the key stays valid, so secondary indexes never need fixing after a split. The cost is that every secondary entry carries a copy of the primary key, so a wide primary key (a UUID string, say) makes every secondary index bigger.
Covering indexes
If every column the query needs is in the entry, there is no second lookup. SELECT id, email ... WHERE email = ? is answered from idx_email alone, and EXPLAIN shows Using index (Demo: covering index). The primary key counts as part of every secondary index, so it is always "covered". This is why a common fix for a slow query is a composite index that also holds the selected columns.
Ranges: neighbouring pages vs random jumps
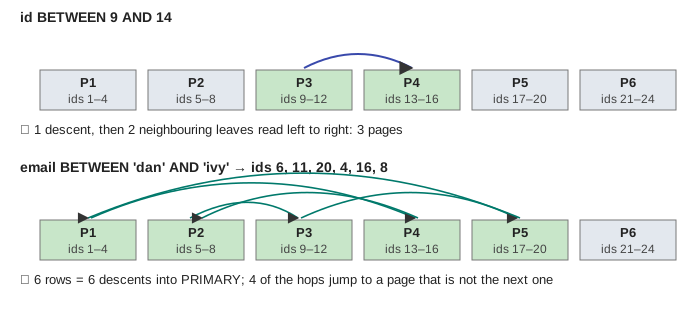
Rows with neighbouring ids sit in the same or the next leaf page, so id BETWEEN 9 AND 14 reads two leaves in order. Rows with neighbouring emails have unrelated ids, so email BETWEEN 'dan' AND 'ivy' walks the secondary leaves in order but then makes one PRIMARY descent per row, jumping between pages (Demo: range by id vs range by email). On a disk that is random I/O; even in memory it is a root-to-leaf search per row.
When the index loses
Without idx_email, finding one email means reading every row of PRIMARY (Demo: email without an index). With it, four pages, and the gap grows with the table. But when a large part of the table matches, one lookup per row costs more than reading all the leaves in order. In Demo: half the table by email, the forced index touches 27 pages against the full scan's 7. The optimizer estimates this from index statistics and switches to a full scan (EXPLAIN type ALL); the cut-off is often a few percent to 20–30% of the rows. MySQL's Multi-Range Read (Using MRR) softens it by sorting the ids before the lookups; see MySQL index access paths.
When each one wins
| Query | Clustered (by id) | Secondary (by email) |
|---|---|---|
One row, SELECT * | 1 tree, 2 pages | 2 trees, 4 pages |
| One row, only indexed columns | 1 tree | 1 tree (covering, Using index) |
| Search on a column with no index | full scan: every row | 4 pages, if the index exists |
| Small range | neighbouring leaves, in order | one descent per row, random jumps |
| Large range (many rows) | full scan in order is cheap | loses to the full scan; the optimizer skips it |
| Cost on writes | insert in key order (auto-increment) fills pages neatly | every index is one more tree to update per insert |
Other databases
PostgreSQL has no clustered index: rows go into a heap in no order, and every index, the primary key included, is a secondary index whose entries point to a row location (a TID). CLUSTER sorts the heap once but does not keep it sorted. SQL Server and SQLite (WITHOUT ROWID) can cluster like InnoDB. See B+ tree as a database index for the heap-file layout and InnoDB page for what is inside one page.
What the page leaves out
The trees have only two levels and tiny pages; real ones have three or four levels with hundreds of entries per page. Pages are counted as logical reads: there is no buffer pool, so a root read twice counts twice, while in practice it stays in memory. The page leaves out the change buffer, adaptive hash index, index condition pushdown, MRR, page splits on insert, prefix and composite indexes, and the cost model the optimizer uses to choose between the lanes.